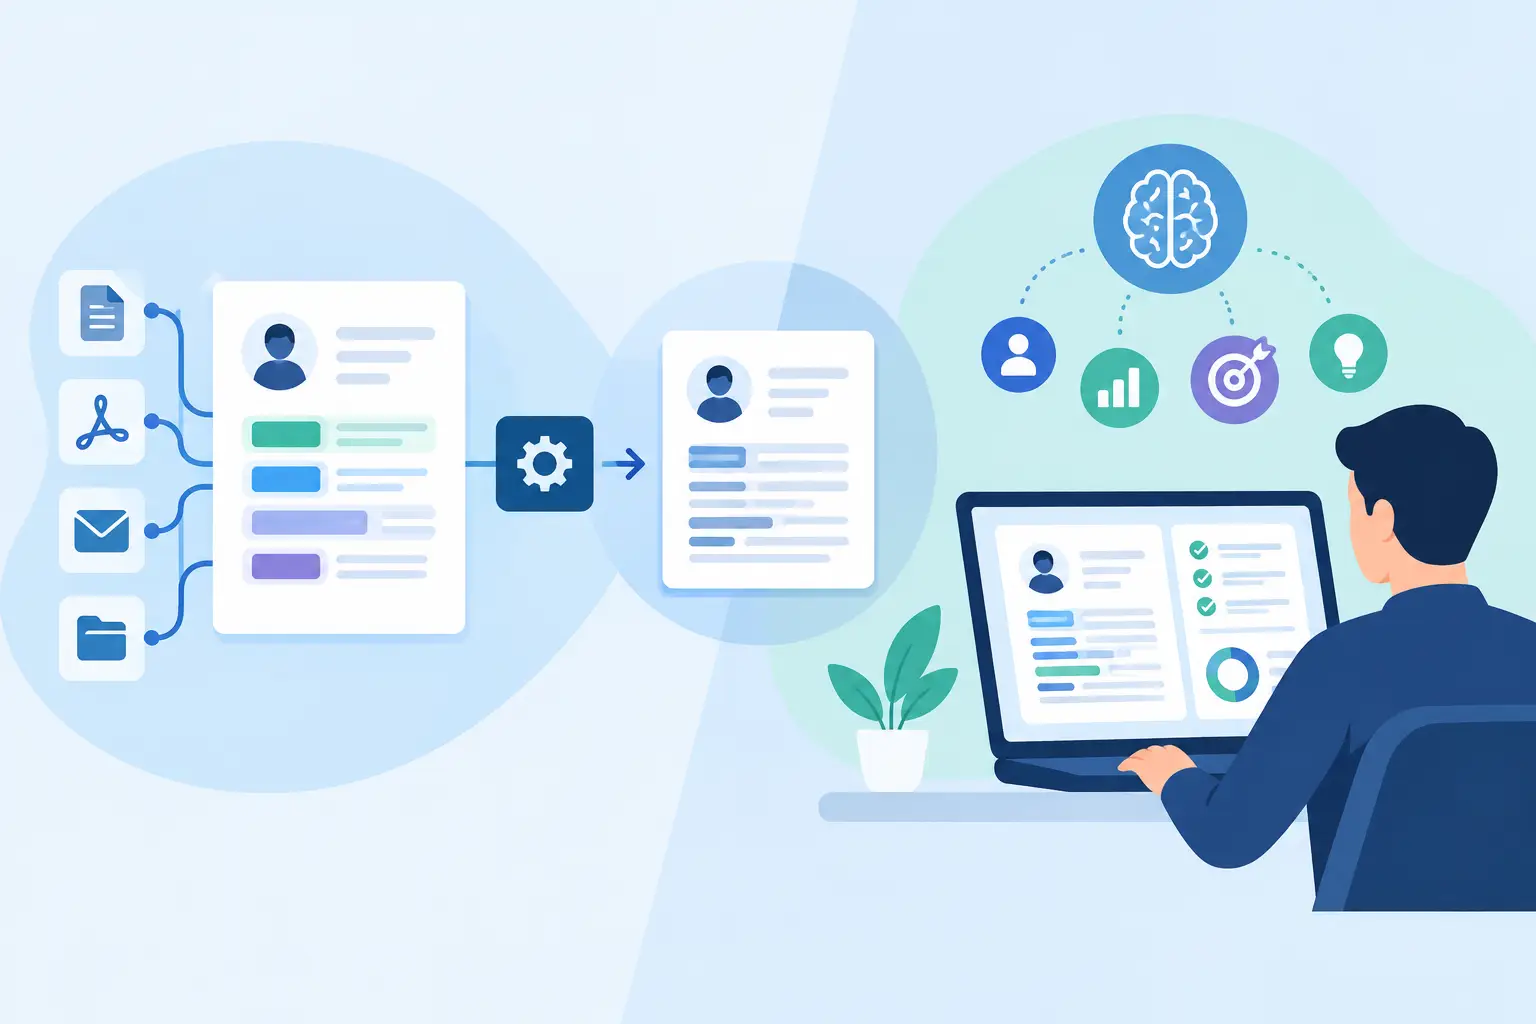
A resume arrives as a PDF, a Word document, or part of a bulk ATS export. The system reads it, extracts the candidate’s name, titles, dates, skills, and education, then places those details into fields. That is useful. But ATS parsing versus resume analysis is not a minor technical distinction. It determines whether your team gets organized records or a defensible view of candidate fit.
Parsing tells you what text appears in a resume. Analysis asks whether the evidence supports the requirements of the role. One creates structure. The other helps recruiters make sense of it.
For high-volume teams, confusing the two creates a predictable problem: a clean candidate profile can look complete while revealing very little about whether someone can do the work. Recruiters still have to open the resume, interpret the claims, compare experience against the actual need, and decide what to test in an interview.
What ATS Parsing Actually Does
ATS parsing converts an unstructured document into searchable data. It identifies likely sections and maps content to fields such as employer, job title, employment dates, degree, certification, location, and listed skills. That makes resumes easier to store, search, filter, route, and report on.
This capability matters. Without it, recruiters are stuck reading every document as a static file. Parsing also supports the basic mechanics of an applicant tracking system: candidate records, talent pools, search filters, duplicate detection, and workflow stages.
But parsers work from document structure and language patterns. They cannot reliably determine the substance behind a claim. A resume may contain “managed enterprise accounts,” “built data pipelines,” or “led a team.” Parsing can capture those phrases. It does not establish account size, technical depth, scope of leadership, results achieved, or whether the experience occurred recently enough to matter.
A parser can also be affected by formatting. Tables, columns, unusual headers, embedded text, scanned files, and inconsistent date formats can produce imperfect extraction. Strong parsing reduces administrative friction. It does not eliminate the recruiter’s interpretive work.
ATS Parsing Versus Resume Analysis: The Operational Difference
Resume analysis begins after the document has been read. It evaluates candidate evidence against standards defined for a specific role. Those standards might include required experience, capability depth, relevant environment, demonstrated outcomes, certifications, management scope, or constraints that matter to the hiring team.
The difference is easiest to see in a familiar search. An ATS can find candidates whose resumes include the phrase “project management.” That search may return an implementation coordinator, a construction project manager, a software delivery lead, and someone who completed a short course. The phrase is present in every record. The relevant experience is not equivalent.
Analysis separates mention from proof. It looks for what the candidate did, in what context, for how long, and with what result. It can also identify where the resume does not provide enough evidence. That is not a rejection decision. It is a prompt for human review and better interview questions.
This distinction matters most when roles are nuanced. A staffing recruiter filling similar jobs for several clients may need to distinguish between exposure and ownership. An internal talent team may need to compare candidates consistently across a large applicant pool. A hiring manager may need to understand why a candidate who looks light on a keyword has strong adjacent experience.
Keyword filters are fast, but they flatten those differences. They can overvalue familiar terminology and miss candidates who describe equivalent work in different language. Resume analysis is designed to restore context.
Why Parsed Data Alone Creates Screening Risk
A structured profile can create false confidence. Fields are filled. Skills are tagged. The candidate appears searchable. Yet a recruiter may still be working from incomplete, ambiguous, or inflated information.
Consider a candidate whose resume lists Python, SQL, and machine learning. Parsing can place all three skills in the record. A keyword match may rank the candidate highly for an analytics role. Analysis asks the questions that matter: Did they use these tools in production? Did they build models or consume them? What business problem did they solve? What evidence shows independent capability rather than coursework or limited exposure?
The same issue appears in leadership hiring. “Managed a team of 10” is not the same as hiring, coaching, setting performance expectations, owning a budget, or leading through change. A recruiter should not have to infer all of that from a title or a single bullet point.
There is also a consistency problem. When every recruiter applies a different mental rubric, the same resume can receive different treatment depending on who reviews it and how much time they have. Parsing standardizes data fields. Analysis can standardize the reasoning applied to evidence.
A Better Workflow: Parse First, Analyze Second
The strongest screening workflow uses both capabilities for what they do best. It does not treat parsing as a substitute for evaluation.
- Ingest and organize the resumes. Parse individual files, bulk uploads, combined PDFs, Word documents, or ATS-fed batches into usable candidate records. Clean inputs make downstream review faster.
- Define the criteria before scoring. Identify what the role actually requires. Separate true requirements from preferences. Be specific about scope, environment, outcomes, and experience that can be verified from the resume.
- Evaluate evidence, not just terms. Review whether the candidate’s work history supports each criterion. Give recruiters a clear explanation of what was found, what is missing, and where the evidence is ambiguous.
- Prepare the interview around uncertainty. Use the analysis to generate targeted questions about claims, gaps, transitions, and relevant accomplishments. The interview becomes a focused validation step, not a second round of basic resume reading.
That workflow preserves recruiter judgment. The system handles repetitive comparison and documentation. The hiring team decides what deserves further consideration and who moves forward.
What Good Resume Analysis Should Produce
A useful analysis output is not a black-box score with no explanation. A number alone cannot tell a recruiter whether the candidate is genuinely strong, unusually relevant, or simply aligned with the vocabulary in a job description.
Look for evidence-backed rankings that show the reasoning behind the result. Recruiters should be able to see how a candidate matched the defined criteria, where their resume did not establish a requirement, and what should be tested in conversation. The explanation should be concise enough to act on and specific enough to defend in a review with a hiring manager.
Controls matter, too. Screening criteria should come from the employer’s defined needs, not recycled job-description language or hidden assumptions. Protected-class criteria should be blocked from the evaluation process. Candidate materials should be handled with clear privacy controls, including encryption and retention practices that fit the workflow.
JAN is built around this model: upload resumes, define the standards, review evidence-backed A-D rankings, and enter interviews prepared. It is decision-support infrastructure, not an autonomous hiring decision-maker. The decision is yours.
When Parsing May Be Enough
Not every workflow needs deep analysis. If a coordinator is checking whether an application contains a required license, confirming geographic eligibility, or organizing a talent database, parsing and simple rules may be sufficient. The goal is administrative accuracy, not comparative judgment.
Analysis becomes more valuable when volume is high, requirements are role-specific, candidate backgrounds vary, or hiring teams need a documented rationale for how resumes were reviewed. It is especially useful when the cost of a missed candidate, an inconsistent screen, or an unfocused interview is high.
The trade-off is straightforward. Deeper analysis requires better-defined criteria. If a hiring team cannot explain what success in the role looks like, no technology can produce a meaningful evaluation. The screening standard has to come first.
The Question Recruiters Should Ask
Do not ask whether your ATS can parse resumes. Most systems can, at least to a degree. Ask what happens after the data lands in the record.
Can your process distinguish a keyword from proven experience? Can it show why one candidate appears better aligned than another? Can it reveal gaps worth testing before the interview starts? Can a recruiter quickly explain the basis for a recommendation without reopening every resume from scratch?
Those are analysis questions. They are where speed becomes judgment support rather than faster administration.
Your next applicant batch does not need another pile of searchable documents. It needs a clear standard, visible evidence, and a recruiter ready to ask the questions that determine whether the resume holds up.